Gain Staging: Why Your Audio Clips and How to Fix It
Gain sets how hard your mic hits the converter, not how loud playback is. Aim for peaks around -12 dBFS, leave headroom, and clipping never happens.
Clipping is the one recording fault nobody can fix later. Room echo can be reduced, a hissy preamp can be replaced, plosives can be edited around. A clipped waveform is a different category of problem: the peaks were never captured in the first place, so there is nothing left in the file to recover. Gain staging is the habit that stops it happening, and it rests on understanding a single number.
What is gain, and why is it not volume?
Gain and volume both change loudness, but they sit at opposite ends of the signal chain and they do opposite jobs. Gain is an input control. It decides how much the incoming microphone signal is amplified before it reaches the analogue-to-digital converter that turns it into a file. Volume is an output control. It decides how loudly the already-recorded signal plays back through your speakers or headphones.
Only one of them is destructive. Turn your monitoring volume down and the recorded file is untouched. Set the gain too high and the file itself is damaged at the moment of recording, before any software gets a chance to intervene.
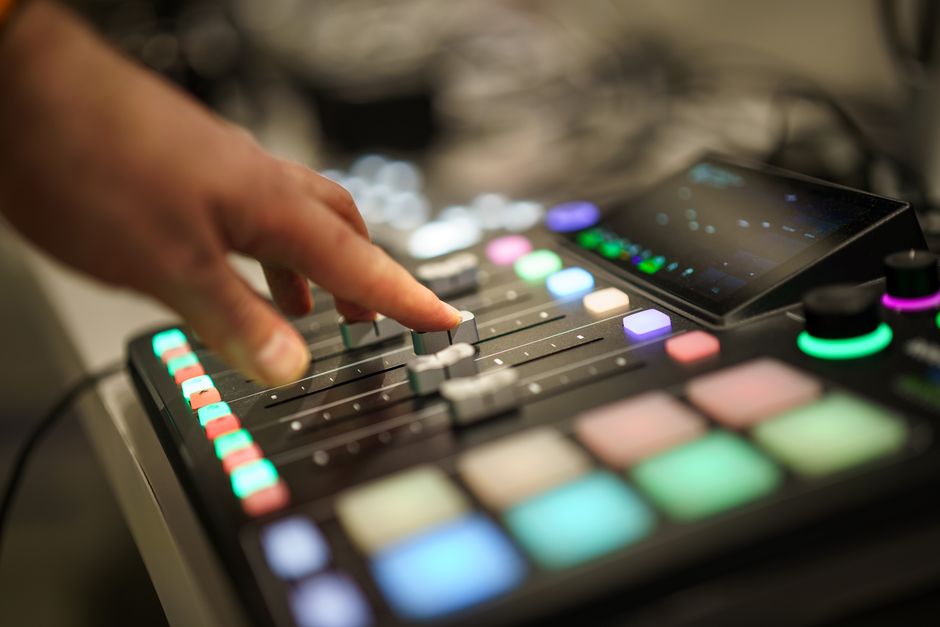
On a USB microphone the gain control is usually a knob on the body or a slider in the manufacturer's companion app. On an audio interface it is the knob beside each XLR input, labelled Gain or Trim. On a mixer it sits at the top of the channel strip, above the fader. The fader below it is not gain: it is a level control positioned after the signal has already been amplified and digitised, which is exactly why pulling it down cannot rescue an input that was too hot on the way in.
Where does the signal actually clip?
Digital audio measures level in dBFS (decibels relative to full scale, a scale on which the maximum representable value is the zero point). Full scale, written 0 dBFS, is the loudest value the system can store. There is no headroom above it, so every usable level is a negative number, and a peak at -6 dBFS is quieter than a peak at -3 dBFS.
Clipping happens when the incoming signal asks the converter for a value beyond 0 dBFS. The converter has no way to represent it, so it stores the largest number it has. The rounded top of the waveform flattens into a straight line, and that flat line is heard as harsh distortion: a crunch or crackle on the loudest syllables, which in speech means the hard consonants, the laughs and the emphasised words.
The part that catches people out is that the excess is not stored somewhere for later. It was discarded during conversion. Reducing the level afterwards produces quieter distortion, not clean audio.
What level should you actually record at?
For spoken word, set gain so peaks land between -12 and -6 dBFS, with the average sitting nearer -18 dBFS. That leaves 6 to 12 dB of headroom above your loudest expected moment, which absorbs a laugh, a raised voice or a lean towards the microphone without reaching 0 dBFS. How much your level moves when you lean or turn depends partly on the capsule's pickup pattern - our polar patterns explainer covers why cardioid punishes drift more than omni.
Peaks close to 0 dBFS are a warning sign rather than a target. A meter that repeatedly touches the top is not a confident recording; it is a recording that survives only as long as nothing surprising happens.
The instinct to record as hot as possible is inherited from tape and from early 16-bit digital, where the converter's own noise floor was close enough to the signal to matter. It no longer applies. At 24-bit, the depth virtually every interface and field recorder now defaults to, the theoretical dynamic range is roughly 144 dB, against about 96 dB at 16-bit. Recording 12 dB below the ceiling costs nothing audible, because the noise floor of your room and your preamp sits far above the noise floor of the converter. The headroom is free; the clipped take is not.
Why can't a clipped recording be repaired?
Repair implies there is something to repair from. When a waveform clips, the samples above full scale are replaced by the maximum value, so the file records a flat plateau where a curve used to be. The shape of that curve is not stored in a lower-priority location or recoverable from surrounding data. It is gone.
Declipping tools in editors such as iZotope RX and Adobe Audition do exist, and they help. What they do is interpolate: they read the slope of the waveform on either side of the plateau and draw a plausible curve across the gap. On short, isolated clips a few samples wide the result can be close to inaudible. On sustained clipping across whole phrases, the tool is inventing a large amount of signal, and it sounds like it.
Treat declipping as damage limitation for a take you cannot record again, never as a reason to be relaxed about levels. The cost of prevention is one careful minute before you press record.
How is analogue gain different from digital normalisation?
Gain is applied in the analogue domain, before conversion. It amplifies the actual voltage arriving from the microphone, so the converter receives a stronger signal and represents it across more of its available range.
Normalisation is arithmetic performed after the fact. It scans a finished file, finds its highest peak, and multiplies every sample by whatever factor lifts that peak to a chosen target. The waveform gets taller; its shape does not change.
That difference has one practical consequence. Normalisation raises the noise floor by exactly as much as it raises the voice, because it multiplies everything in the file equally. Getting gain right at the source improves the ratio between your voice and the noise; normalising afterwards preserves whatever ratio you already had. This is why "record quiet and fix it later" holds only within limits. At 24-bit you can lift a conservatively recorded take substantially before noise becomes distracting, but a take recorded 40 dB too low will bring the room's hum, the fridge and the preamp hiss up with the voice.
How do loudness targets change what you do?
Peak level and perceived loudness are separate measurements, and conflating them causes a lot of avoidable confusion. dBFS describes the height of individual peaks. LUFS (loudness units relative to full scale) describes how loud material sounds to a listener averaged over time, which tracks human hearing far more closely.
EBU R 128, the European Broadcasting Union's loudness recommendation, sets a programme target of -23 LUFS with a permitted deviation of plus or minus 0.5 LU, and requires that the programme never exceeds a true peak of -1 dBTP. Streaming platforms normalise louder: Spotify's published podcast guidance is -14 LUFS with a -1.0 dBTP ceiling, and Apple Podcasts asks for -16 LUFS within about 1 dB.
None of those figures is a recording target. Every one of them describes a finished, mastered file at the point of delivery, reached through compression and limiting during the mix. Your tracking levels do not move to meet them. You still record with peaks around -12 dBFS and headroom intact, then set loudness at the end, where a mistake costs an export rather than the take.
The practical routine, start to finish
Fix microphone position before touching gain
Distance changes level more dramatically than the gain knob does. Settle on your working distance first, typically a hand's width from a dynamic microphone, then set gain to suit it.
Start with gain at minimum
Turn the control fully down, then bring it up. Starting high and reducing means your first test is the one at risk of clipping.
Speak your script, not a level check
Read real sentences at real presenting energy while you watch the meter. This single habit prevents most clipped takes.
Raise gain until peaks sit near -12 dBFS
Watch where the loudest words land rather than where the needle spends most of its time. The average will settle around -18 dBFS on its own.
Provoke your loudest moment deliberately
Laugh, raise your voice, deliver the line you know you will get excited about. If that reaches 0 dBFS, take 3 dB off and test again.
Record twenty seconds and look at the waveform
Flat tops anywhere mean the gain is still too high. A waveform that fills roughly half the track height is right.
Leave the gain alone for the rest of the session
Adjusting mid-take produces a recording with inconsistent level that is harder to process than one recorded slightly quiet throughout.
Common gain-staging mistakes
Setting levels in a mumble
The most common cause of clipping. Levels checked at conversational volume are wrong by several decibels the moment you switch into presenting mode.
Treating 0 dBFS as the goal
Full scale is a wall, not a finish line. Nothing improves as peaks approach it, and everything is lost when they cross it.
Using the fader to fix an input problem
A fader operates after conversion, so it lowers distortion rather than removing it. Fix input level at the gain stage.
Stacking gain in three places at once
Interface gain, an input trim in your recording software, and a plugin on the channel all multiply. Set gain once, at the source, and leave the rest at unity.
Riding the gain knob mid-take
Level changes recorded into the file cannot be undone cleanly. Ride the performance instead, or compress in the edit.
Normalising before you edit
Normalisation reads the highest peak in the file. Do it before removing a cough or a chair scrape and the whole track is scaled to that noise.
Frequently asked questions
What dB level should I record my voice at?
Is -6 dBFS too loud to record at?
Can you fix a clipped recording?
Should I use the pad or limiter on my microphone or interface?
Is automatic gain control a good idea for podcasts?
Does 24-bit recording mean gain matters less?
Soundproofing vs Acoustic Treatment: What Actually Differs
Best Acoustic Panels for an Echoey Home Office
A Complete First Podcast Kit Under £300